
Architecting Global Caching Layers for Low-Latency AI Inference
In the transition from experimental artificial intelligence to production-grade enterprise deployment, technical leadership faces a brutal reality: generative AI is inherently constrained by the laws of physics and economics. The computational intensity required to serve large language models (LLMs) at scale creates a systemic bottleneck. Every time a user submits a prompt, an intricate dance of matrix multiplications occurs across expensive GPU clusters, consuming immense memory bandwidth and processing power. When deployed globally without strict infrastructure optimization, the financial cost of this compute skyrockets, while the end-user experience degrades under the weight of severe latency.
The solution to this intelligence bottleneck is not simply provisioning more hardware. The solution lies in fundamentally restructuring how requests are handled before they ever reach the foundational model. For the autonomous enterprise, the implementation of AI inference caching is a non-negotiable architectural mandate. By intercepting redundant and semantically similar queries at the perimeter of your network, enterprise architects can drastically slash operational costs, achieve near-instantaneous response times, and preserve mission-critical GPU resources for novel, high-complexity tasks.
This technical brief deep-dives into the mechanics of architecting global caching layers, moving beyond rudimentary web caching to sophisticated semantic retrieval systems. We will explore the deployment of vector similarity caches, high-performance in-memory datastores, and edge-native routing protocols required to scale AI profitably.
The Financial and Operational Crisis of Redundant GPU Compute
To understand the necessity of a caching layer, one must first analyze the anatomy of LLM inference overhead. Modern generative models are memory-bound. The primary bottleneck is not the speed at which the GPU’s Tensor Cores can process math, but rather the speed at which the High Bandwidth Memory (HBM) can feed weights and the Key-Value (KV) cache into the processors. This is known as the memory wall.
In a standard, uncached enterprise deployment, an organization might have hundreds or thousands of users interacting with an internal AI assistant, summarizing financial reports, querying documentation, or generating code. Human behavior is highly repetitive. It is common for dozens of users to ask the AI slightly varied versions of the exact same question, such as: “What is our Q3 revenue projection?” or “Give me the revenue forecast for the third quarter.”
Without an AI inference caching layer, the system routes every single one of these requests to the LLM. The GPU cluster must process the prompt, allocate memory for the new KV cache, and auto-regressively generate tokens one by one. This redundancy results in two catastrophic operational failures:
- Uncontrolled Infrastructure Spend: GPU compute is the most expensive line item in modern IT budgets. Computing the exact same semantic answer repeatedly is a massive waste of capital, rapidly depleting cloud budgets and leading to negative ROI on AI initiatives.
- Degraded User Experience: As concurrent requests queue up at the inference server, the system experiences continuous batching delays. The Time-To-First-Token (TTFT)—the critical metric defining how responsive an AI feels to the user—spikes from acceptable millisecond ranges into multi-second delays, destroying the fluidity of the application.
To fundamentally reduce GPU compute overhead, the architecture must intercept these redundant queries. However, because human language is infinitely variable, traditional IT caching mechanisms are entirely useless for generative AI.
Moving Beyond Traditional Systems: The Vector Similarity Cache
In classic web architecture—such as caching HTML pages, CSS files, or API JSON payloads—caching relies on exact string matching. A CDN or proxy server evaluates a URL or a precise database query. If `Request A` perfectly matches `Request B`, the cached asset is served. If a single character is different, it registers as a cache miss.
In the realm of LLMs, exact string matching is inadequate. “How do I reset my password?” and “What are the steps to change my login code?” are entirely different strings, yet they carry the exact same semantic intent and require the exact same generated answer. To solve this, the autonomous enterprise must deploy a vector similarity cache.
A vector similarity cache does not store data based on text strings; it stores data based on mathematical meaning. When a user submits a prompt, the caching architecture executes the following process:
- Vector Embedding Generation: The raw text prompt is instantly routed to a lightweight, highly optimized embedding model (such as OpenAI’s text-embedding-3-small, or an open-source alternative like BGE-M3 or sentence-transformers deployed locally). This model translates the text prompt into a high-dimensional array of floating-point numbers (a vector).
- Semantic Search: The cache system compares this new vector against a database of previously answered vectors. Instead of looking for an exact match, it calculates the mathematical distance between the vectors using algorithms like Cosine Similarity, Euclidean Distance, or Dot Product.
- Threshold Evaluation: The Enterprise Architect defines a strict confidence threshold (e.g., 0.95 or 95% similarity). If the incoming prompt vector is 95% similar to a previously stored vector, the system registers a “Semantic Cache Hit.”
- Instant Retrieval: The caching layer immediately returns the previously generated LLM response associated with that vector, completely bypassing the heavy inference GPU cluster.
By mapping language into high-dimensional space, the infrastructure can intelligently recognize intent, intercepting up to 30-40% of standard enterprise AI traffic before it ever touches a heavy foundational model.
Architecting the Core: Redis Vector Search and High-Performance Stores
The effectiveness of a vector similarity cache hinges entirely on its speed. If the process of embedding the prompt and searching the vector database takes longer than routing the request to the LLM, the cache becomes a bottleneck rather than an accelerator. Therefore, the underlying data store must be optimized for ultra-low latency, in-memory operations.
While disk-backed vector databases (like Pinecone, Milvus, or Qdrant) are excellent for long-term Retrieval-Augmented Generation (RAG) document storage, the inference caching layer requires in-memory speeds. Redis vector search (often deployed via Redis Enterprise with the RediSearch module or open-source alternatives like Valkey) has emerged as a premier architectural standard for this specific workload.
When architecting the Redis vector search tier, technical leaders must make critical decisions regarding the indexing algorithm used to map the vector space:
- FLAT (Brute Force) Indexing: This algorithm compares the incoming vector against every single vector in the cache. It guarantees 100% accuracy in finding the closest match but scales poorly. As the cache grows to millions of responses, FLAT indexing latency increases linearly, eventually defeating the purpose of the cache.
- HNSW (Hierarchical Navigable Small World) Indexing: For enterprise scale, HNSW is the mandatory standard. It is an Approximate Nearest Neighbor (ANN) algorithm that builds a multi-layered graph of vectors. HNSW trades a fraction of a percent of accuracy for massive, logarithmic speed increases, allowing the Redis cluster to search millions of cached AI responses in single-digit milliseconds.
By standardizing on an in-memory store utilizing HNSW indexing, the architecture ensures that the overhead of semantic routing remains virtually imperceptible to the end-user.
Pushing Intelligence to the Perimeter: Edge AI Deployment
Solving the compute bottleneck is only half of the latency equation; the other half is geographical network latency, constrained by the speed of light. If a user in London queries an enterprise AI system hosted in a centralized AWS us-east-1 data center in Virginia, they will incur hundreds of milliseconds of round-trip network latency before the GPU even begins processing the request.
To build a truly global autonomous enterprise, the caching layer must be decentralized. This requires a robust edge AI deployment strategy. Similar to how traditional Content Delivery Networks (CDNs) cache static assets at the network edge close to the user, enterprise AI architectures must push vector caching and embedding generation to the perimeter.
In an advanced edge AI deployment, the architecture looks like this:
- Edge Compute Nodes: Leveraging serverless edge environments (such as Cloudflare Workers, Fastly Compute, or distributed Kubernetes edge clusters), the enterprise deploys lightweight embedding models directly at edge Points of Presence (PoPs) globally.
- Distributed In-Memory Caches: A globally distributed, heavily synchronized key-value store (like DynamoDB Global Tables or a geo-distributed Redis cluster) sits alongside the edge compute nodes.
- Localized Interception: When the user in London submits a prompt, it hits the London edge node. The edge node instantly vectorizes the prompt and queries the local London read-replica of the vector cache. If there is a semantic hit, the answer is returned from London in under 20 milliseconds.
Only if the request results in a semantic cache miss does the edge node forward the prompt across the ocean to the centralized, heavy GPU cluster for deep inference. This decoupling of the request pipeline—handling repetitive queries at the edge and novel queries at the core—is the defining characteristic of architectural scalability.
The Request Lifecycle: Implementing the Automated Pipeline
Integrating a global AI inference cache requires meticulous orchestration. The system must seamlessly route traffic, evaluate similarity thresholds, and handle fallback procedures without manual intervention. The pipeline operates as an automated state machine:
- Ingestion and Normalization: The API Gateway receives the JSON payload containing the user’s prompt. The system normalizes the text (removing whitespace, standardizing casing, and stripping unnecessary punctuation) to improve vector matching accuracy.
- Concurrent Pipeline Execution: To minimize TTFT, the system triggers the embedding generation via the lightweight model while simultaneously running moderation and safety filters.
- Vector Query Execution: The generated vector is passed to the Redis vector search engine. The engine executes an HNSW nearest-neighbor search, returning the top matched vector and its similarity score.
- Decision Routing: If the similarity score exceeds the predefined threshold (e.g., > 0.94), the orchestrator retrieves the paired LLM text response from the cache payload and streams it back to the user.
- Inference Fallback and Cache Population: If the score is below the threshold, the orchestrator routes the normalized prompt to the heavy LLM cluster (e.g., Llama 3 or GPT-4). As the LLM streams the response to the user, a background asynchronous webhook captures the final response text, pairs it with the initial prompt’s vector, and writes it back to the Redis cache for future use.
By relying on webhook-driven, asynchronous background tasks for cache population, the architecture ensures that the critical path of generating the user’s response is never blocked by database write operations.
Cache Invalidation and Dynamic Contexting in RAG Ecosystems
Caching AI responses introduces a complex challenge: data staleness. In a Retrieval-Augmented Generation (RAG) system, an LLM generates answers based on internal enterprise documents, databases, and APIs. If the underlying data changes, the cached AI response becomes factually incorrect and dangerous to operational integrity.
For example, if an employee queries, “What is our standard IT onboarding procedure?”, and the cache stores the response based on the 2025 manual, that cached response must be systematically destroyed the moment the 2026 manual is published.
Advanced AI caching architectures must implement deterministic cache invalidation strategies:
- Time-to-Live (TTL) Decay: The simplest method involves assigning strict expiration timers to cached responses. High-volatility topics (like live inventory queries) might have a TTL of 5 minutes, while static topics (like historical company background) might have a TTL of 30 days.
- Event-Driven Invalidation: A more robust approach integrates the caching layer directly with the enterprise data pipeline. When a document is updated in the central knowledge base (e.g., SharePoint or Confluence), an automated n8n webhook or Kafka event triggers a targeted purge in the Redis cache, deleting all vector-response pairs associated with that document’s semantic metadata.
Measuring Success: Telemetry, TTFT, and Quantifiable ROI
The deployment of a vector similarity cache is not a theoretical exercise; it must be justified by rigorous telemetry and financial analysis. Enterprise architects must instrument the API gateway to track the cache hit ratio (CHR). A healthy, mature enterprise AI deployment should aim for a CHR between 20% and 40%, depending on the uniformity of user tasks.
The financial return on investment (ROI) is calculated by multiplying the CHR by the cost of LLM inference tokens. If a heavy GPU cluster costs $0.01 per 1,000 generated tokens, and the cache intercepts 1 million redundant queries a day averaging 500 tokens each, the architecture saves thousands of dollars per month in raw compute costs, while simultaneously freeing up cluster capacity to serve more concurrent users without requiring hardware expansion.
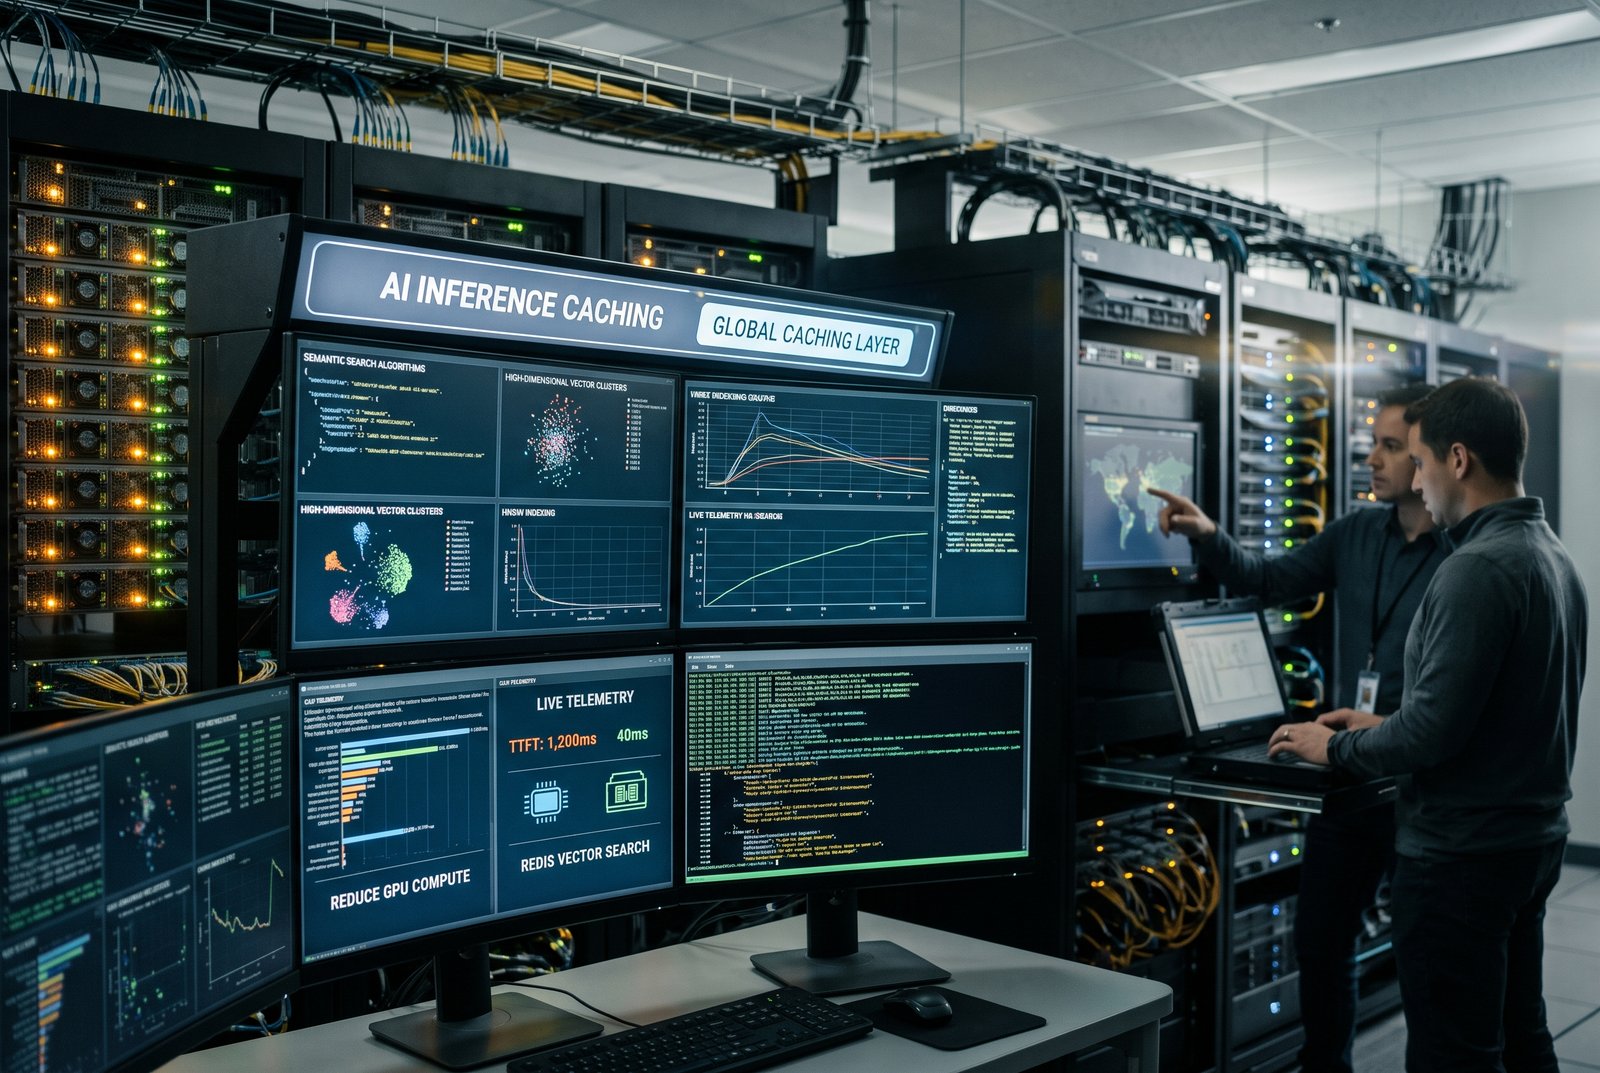
Equally important is the operational ROI measured in Time-to-First-Token (TTFT). Deep inference on a heavy LLM might result in a TTFT of 1,200 milliseconds. A semantic cache hit from a geographically optimized edge node can return a TTFT of under 40 milliseconds. This 30x reduction in latency transforms the AI from a sluggish analytical tool into a hyper-responsive operational asset.
Conclusion: The Imperative of Efficient AI Scaling
The era of treating generative AI as a monolithic black box is over. As organizations scale, the failure to decouple the AI request pipeline into distinct, optimized layers will result in catastrophic infrastructure costs and unacceptable latency.
By architecting a robust AI inference caching layer—powered by vector similarity search, high-speed memory stores, and intelligent edge deployments—technical leaders can successfully tame the compute requirements of modern language models. This strategic implementation is the first foundational pillar in transforming a standard IT operation into a truly resilient, scalable, and cost-efficient autonomous enterprise.

Leave a Reply